My research aims to advance efficient and scalable AI through algorithmic innovation in efficient modeling and the design of high-performance machine learning systems. I currently focus on training and inference for multimodal content generation, addressing computational and memory bottlenecks to enable high-quality, long-horizon generation in real time.
I earned my Ph.D. at UC Santa Barbara, where I was fortunate to work with Prof. Peng Li (IEEE Fellow). Before UCSB, I completed my M.S. at the University of Michigan, Ann Arbor, where I had the pleasure of working with Prof. David Blaauw and Prof. Dennis Sylvester. I received my B.S. from the University of Electronic Science and Technology of China.
My work received consecutive William J. McCalla Best Paper Award nominations at ICCAD 2024 and 2025. I was awarded the Radhakrishnan Nagarajan Family Fellowship at UC Santa Barbara and won the Second Place at the DAC 2026 Ph.D. Forum.
Explored Video Sparse Attention for MovieGen-30B, focusing on serving inference acceleration and large-scale sparse distribution matching distillation on hundreds of GPUs.
Explored Multi-teacher knowledge distillation for multi-modal and multi-task foundation models supporting integrity detection across Facebook, Instagram, and WhatsApp.
I have published in leading conferences and journals in machine learning, computer architecture, and design automation, including ISCA, NeurIPS, AAAI, CVPR, ICCV, ICCAD, TCAD, and JSSC.
Boxun Xu, Yuming Du, Zichang Liu, Siyu Yang, Ziyang Jiang, Siqi Yan, Rajasi Saha, Albert Pumarola, Wenchen Wang, Peng Li
Preprint 2026
Long-horizon video generation needs persistent visual memory without the cost of dense attention. First native trainable sparse attention for autoregressive video diffusion to make video generation both faster and better.
Conference on Neural Information Processing Systems (NeurIPS), 2026
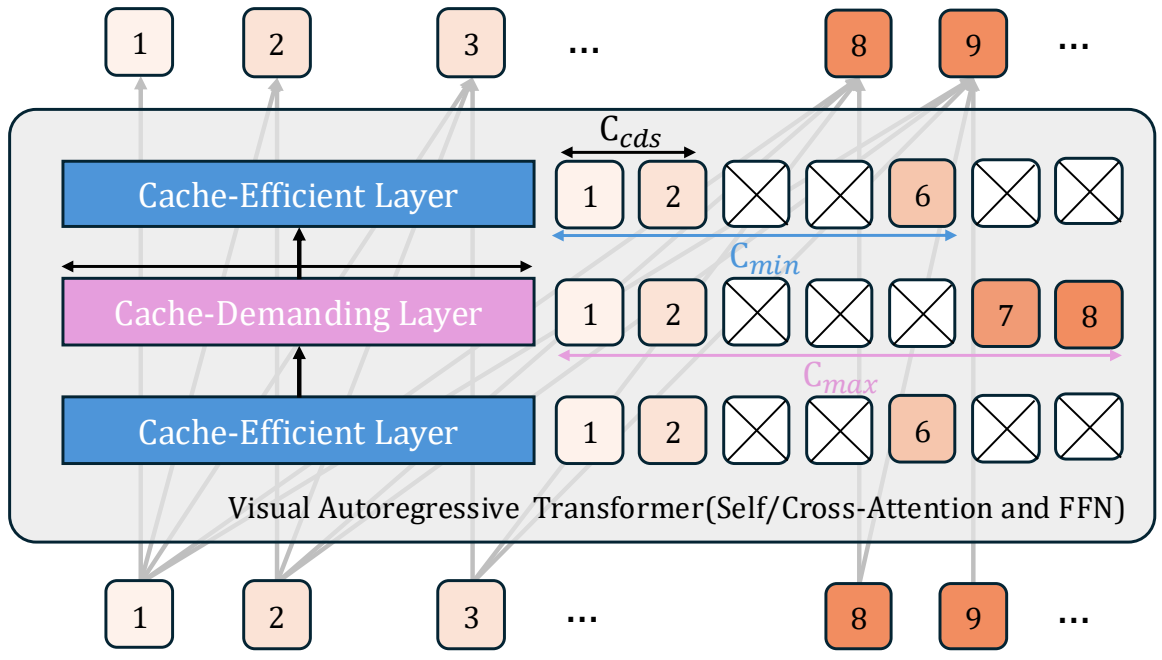
Large KV caches limit the scalability of autoregressive image and video generation. First tuning-free KV-cache quantization for visual autoregressive generation, evaluated across nine image and video models.
AMS-KV: Adaptive KV Caching in Multi-Scale Visual Autoregressive Transformers
Boxun Xu, Yu Wang, Zihu Wang, Peng Li
AAAI Conference on Artificial Intelligence (AAAI), 2026
Different layers and image scales need different cache budgets to preserve generation quality. First adaptive KV-caching framework tailored to multi-scale visual autoregressive transformers.
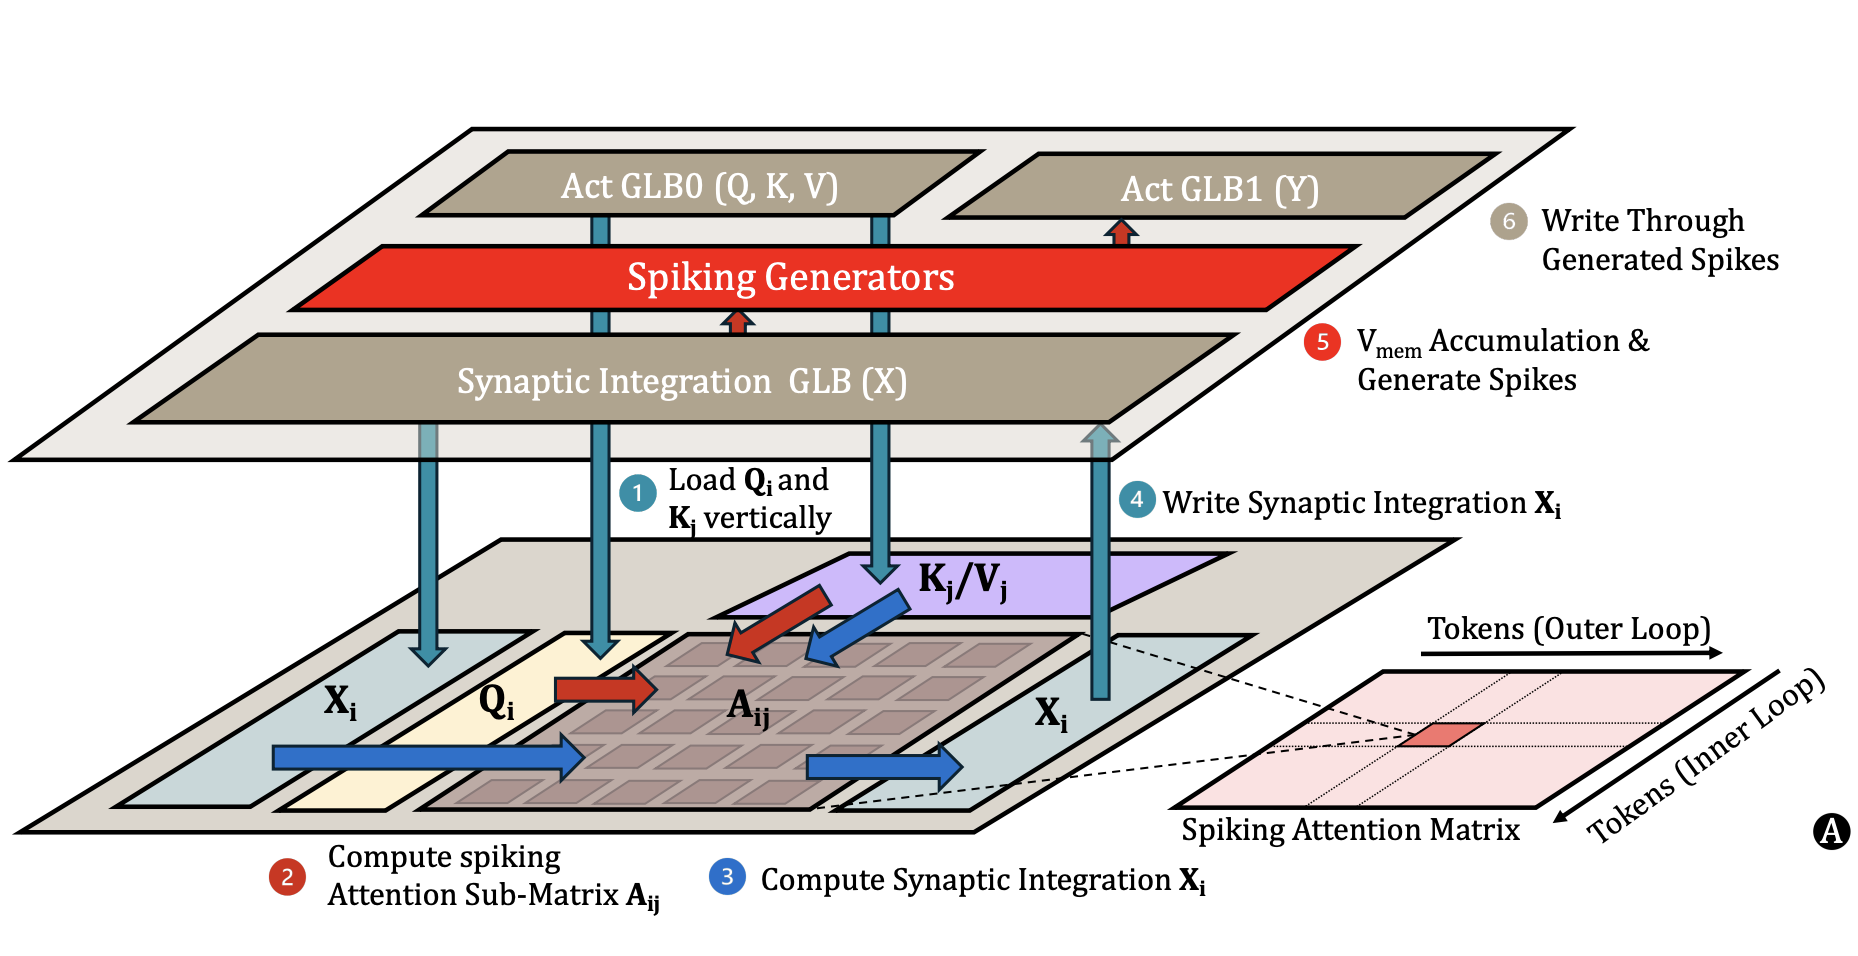
Bishop: Sparsified Bundling Spiking Transformers on Heterogeneous Cores with Error-Constrained Pruning
Boxun Xu, Yuxuan Yin, Vikram Iyer, Peng Li
International Symposium on Computer Architecture (ISCA), 2025
Spiking transformers produce workloads with different activity densities across tokens and time. First heterogeneous HW/SW co-design framework for brain-inspired neuromorphic transformers.
ACM/IEEE International Conference on Computer-Aided Design (ICCAD), 2025
🏆 William J. McCalla Best Paper Award Nomination
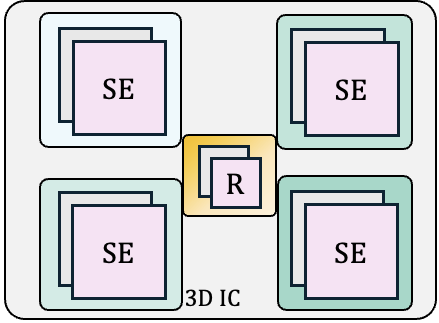
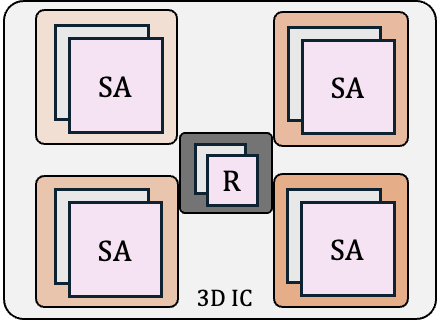
Mixture-of-experts expands model capacity through conditional computation, creating a need for parallel, distributed hardware. First 3D distributed and parallel accelerator for spiking MoE and multi-head attention.
Spiking Transformer Hardware Accelerators in 3D Integration
Boxun Xu, Junyoung Hwang, Pruek Vanna-iampikul, Sung-Kyu Lim, Peng Li
ACM/IEEE International Conference on Computer-Aided Design (ICCAD), 2024
🏆 William J. McCalla Best Paper Award Nomination
Spiking transformers combine attention with binary spike operations, but require dedicated hardware to realize their efficiency. First dedicated 3D accelerator for brain-inspired neuromorphic transformers.
AIMMI: Audio and Image Multi-Modal Intelligence via a Low-Power SoC With 2-MByte On-Chip MRAM for IoT Devices
Zichen Fan, Qirui Zhang, Hyochan An, Boxun Xu, Li Xu, Chien-Wei Tseng, Yimai Peng, Andrea Bejarano-Carbo, Pierre Abillama, Ang Cao, Bowen Liu, Changwoo Lee, Zhehong Wang, Hun-Seok Kim, David Blaauw, Dennis Sylvester